Machine Learning Platform Engineer Career Roadmap
Machine Learning Platform Engineers build the internal tools other ML engineers and data scientists live inside every day — feature stores, model registries, experiment tracking, the SDK that turns "train a model" from a bespoke science project into a repeatable, supportable process. The clearest way to understand the role, borrowed from how practitioners actually describe it: an MLOps engineer operates models in production — deployment, monitoring, retraining, drift. A platform engineer builds the reusable system that MLOps and ML engineers both work inside. If you'd rather unblock twenty other engineers than personally ship one more model, this is the job.
Is this the right path for you?
Machine Learning Platform Engineers almost always arrive from a software engineering background, not a data science one — backend engineers who gravitate toward ML-adjacent infrastructure, or ML/MLOps engineers who realise they'd rather build the tool than operate the model. Genuine entry-level hires into this exact title are rare; real postings consistently expect production-systems experience most new graduates haven't had time to build yet.
The clearest real distinction, borrowed from how practitioners actually describe it: an MLOps engineer operates models in production — deployment, monitoring, retraining, drift. A platform engineer builds the reusable system that MLOps and ML engineers both work inside — the feature store, the registry, the serving layer, the SDK. If you get more satisfaction from unblocking twenty other engineers than from personally shipping one more model, you're already thinking like this role wants you to.
Honest note: this is a software-engineering-heavy specialisation wearing an "ML" label — the actual daily work is API design, distributed systems, and developer-experience thinking, with just enough ML-specific vocabulary to require you to speak the language of the engineers you're building for. People expecting to spend their time on model architecture or research are usually disappointed; people who like building infrastructure other engineers depend on daily tend to thrive.
Career Progression
Where does this role lead?
Click any role to explore timeline, key skills and, where the Department of Labor publishes it, pay.
Entry
ML Platform Engineer
~1–2 yrs
$74,464 (Level I)
You're extending an existing platform under guidance — usually arriving with a software engineering background rather than starting from zero.
Key skills
Pay shown is the U.S. Department of Labor prevailing wage for Level I (entry), Level III (mid) and Level IV (senior) in the nearest BLS occupation, base wage for the typical metro, wage year 2025, shown for the main track only. It is a benchmark, not an offer; branches and lead, staff and executive stages have no official figure.
Visual roadmap
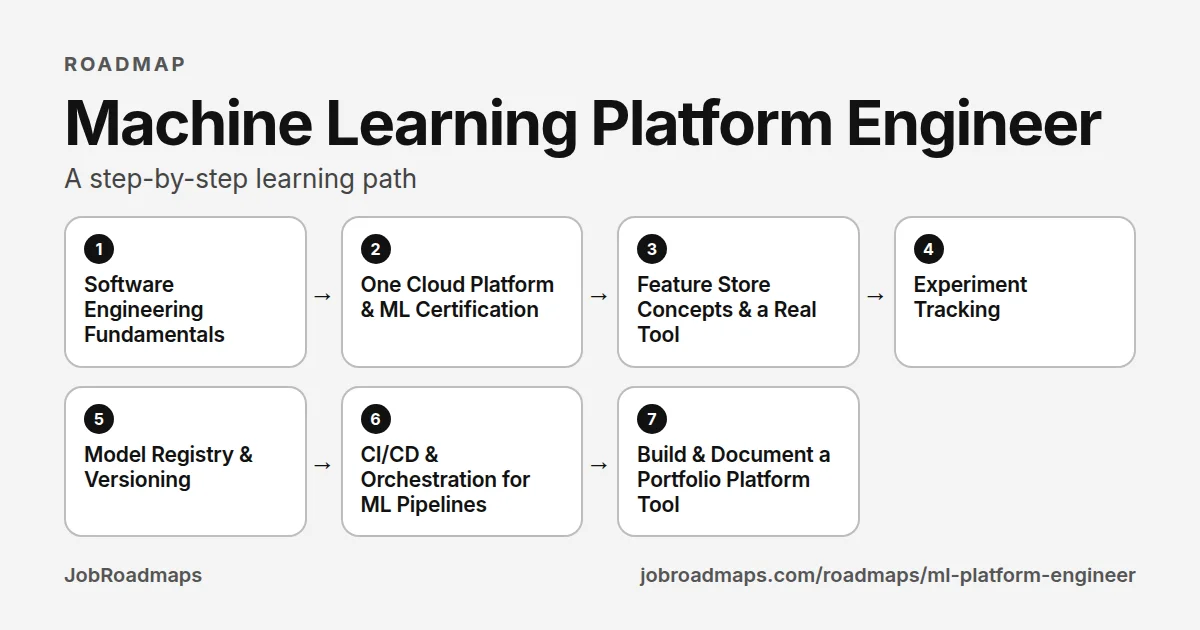
Machine Learning Platform Engineer learning path
Work down the line, one step at a time. Tick each skill as you can do it.
- 1
Software Engineering Fundamentals
6–8 weeksThis role is software engineering first, ML-flavoured second. Real postings (Reddit's ML Feature Platform team especially) expect fluency in API design and distributed systems basics before any ML-specific tooling knowledge.
Skills to learn
- API design
- Distributed systems basics
- Python (deep)
- Go or Scala (common secondary language)
- Git & code review
Start with
- 2
One Cloud Platform & ML Certification
4–6 weeksPick one major cloud (AWS, GCP, or Azure) and pair it with that platform's ML certification. Databricks' Machine Learning Associate cert is the single most directly relevant credential here — its exam explicitly covers feature stores and MLflow.
Skills to learn
- One major cloud platform (AWS/GCP/Azure)
- Cloud ML services overview
- Databricks Unity Catalog Feature Store
Start with
- 3
Feature Store Concepts & a Real Tool
4–5 weeksThe feature store is the platform's centrepiece — a central, reusable repository of ML features shared across teams. Learn the concept, then get hands-on with Feast (open-source, self-managed) or understand Tecton (managed, sub-100ms serving).
Skills to learn
- Feature store architecture
- Feast (open-source feature store)
- Tecton (managed feature platform)
- Online vs. offline feature serving
Start with
- 4
Experiment Tracking
3–4 weeksMLflow and Weights & Biases are the two dominant real tools across every posting found — learn to instrument training runs, compare experiments, and make results reproducible for the ML engineers who'll depend on your platform.
Skills to learn
- MLflow tracking
- Weights & Biases
- Experiment reproducibility
- Metric logging & comparison
Start with
- 5
Model Registry & Versioning
3 weeksA model registry is how a platform tracks which model version is in production, staging, or archived — reinforced directly in Databricks' ML Associate certification content.
Skills to learn
- MLflow Model Registry
- W&B Models
- Model versioning & lineage
- Staging → production promotion workflows
Start with
- 6
CI/CD & Orchestration for ML Pipelines
5–6 weeksOrchestration tools that come up repeatedly in real postings: Kubernetes, Kubeflow, Metaflow, Argo Workflows, and Ray. Learn at least one deeply enough to build a CI/CD pipeline for a model end to end.
Skills to learn
- Kubernetes basics
- Kubeflow or Metaflow
- Argo Workflows
- CI/CD for ML pipelines
Start with
- 7
Build & Document a Portfolio Platform Tool
4–6 weeksBuild a mini feature store or training-orchestration tool with real documentation — README, API docs, architecture diagram. This directly mirrors what real postings ask candidates to demonstrate: "build the reusable system... the feature store, the registry, the serving layer, the SDK."
Skills to learn
- End-to-end platform tool design
- API/SDK documentation
- Architecture diagramming
- Explaining design trade-offs in interviews
Start with
jobroadmaps.com/roadmaps/ml-platform-engineer · Pay, demand and employer data for this role are further down the page.
Job Market Insights for Machine Learning Platform Engineer
Data-backed
Which skills appear most in job postings?
Read from live job postings, ranked from most to least often named.
observability leads the list and is named frequent. If you are only going to learn one thing before applying, the postings say start here.
Past the fundamentals, 4 specialisation skills (observability among them) appear in a minority of postings. Not universal, but the kind of depth that makes a hiring manager stop skimming.
Skill
How often named
observability
model training
model serving
cloud-native architecture
Sorted by how often named · JobRoadmaps
Industry overlay
Targeting a specific industry?
The core roadmap gets you through the door anywhere. The difference between "qualified" and "they hired someone else" often lives in industry-specific context — the norms, the compliance floors, the tools assumed fluent in that sector.
platform as a product
Roblox explicitly asks for APIs, SDKs and CLIs that internal teams adopt quickly.
model evaluation
Safety and moderation models must be evaluated and monitored continuously.
AI agents
Riot's AI Efficiency team builds guardrailed tooling for internal AI use.
Companies hiring:
Riot GamesRobloxstream processing
Fraud detection needs real-time features computed from transaction streams.
reliability engineering
Highly available inference is required because outages affect customers' money.
access control
Financial data and models require strict permissions and audit controls.
Companies hiring:
CoinbaseIndustry premiums based on aggregated job posting data · Updated quarterly
Interactive
How ready are you right now?
Check the skills you already have to see your current job-market fit.
The most-named skill for this role is observability, so a gap there costs you the most. Skills at the top of the scale appear across most postings, so a single gap there narrows your options more than a gap in a rarer skill. Check what you already have to see your biggest current gap.
Readiness Check
Check the skills you already have
0/4
base skills
Your biggest gap: observability, the most often named of the skills you have not ticked.
Start there, then work down the list.
Books worth reading as a Machine Learning Platform Engineer
Where to start, in order. The full list of 12, grouped by career stage, is on its own page.
Getting started

Hands-On Machine Learning with Scikit-Learn, Keras, and TensorFlow
by Aurélien Géron · 2017
~860 pages~22 hrs to read
A code-first introduction to classical ML and deep learning. Read it to understand what your users train and what they need from the platform.
View book →
Designing Machine Learning Systems
by Chip Huyen · 2022
~390 pages~10 hrs to read
Covers data pipelines, feature engineering, deployment and monitoring for production ML. A map of the problems an ML platform exists to solve.
View book →
Doing the job

Building Machine Learning Pipelines
by Hannes Hapke, Catherine Nelson · 2020
~340 pages~9 hrs to read
Shows how to automate the model lifecycle (data validation, training, serving and orchestration) with TensorFlow Extended. Read it when you build reusable pipelines for other teams.
View book →Machine Learning Design Patterns
by Valliappa Lakshmanan, Sara Robinson, Michael Munn · 2020
~400 pages~10 hrs to read
Catalogues recurring solutions for data, training, serving and reproducibility problems. Useful when you design platform features such as feature stores and model registries.
View book →
Senior and leading

Platform Engineering: A Guide for Technical, Product, and People Leaders
by Camille Fournier, Ian Nowland · 2024
~330 pages~8 hrs to read
Covers how to run an internal platform as a product: scope, team structure, adoption and measurement. Directly applicable to an ML platform with internal users.
View book →
Team Topologies
by Matthew Skelton, Manuel Pais · 2019
~240 pages~6 hrs to read
Describes team types and interaction modes for fast flow, including platform and enabling teams. Read it when you decide how the ML platform team works with data science teams.
View book →
All 12 books for a Machine Learning Platform Engineer →Browse all books →
Some book links are affiliate links: we earn a small commission if you buy, at no cost to you. It does not affect what we list.
Prerequisites & Education
What credentials do employers look for?
These are the most common paths into this role — no single one is required.
Education Level
View list — coming soon- Bachelor's in Computer Science or Software Engineering — the standard baseline
- Bachelor's in a related quantitative field with strong software engineering skills
- Self-taught with genuine production-systems experience — viable, but rarer than in web development
- No dedicated degree path exists for this specialisation — it sits inside general software engineering, not a separate academic field
Real postings consistently emphasise production-systems and distributed-systems experience over ML-theory coursework — this is a software engineering role wearing an ML-adjacent label, and hiring reflects that.
Certifications
View list — coming soon- Databricks Certified Machine Learning Associate — the single most directly relevant certification; its exam explicitly covers feature stores (Unity Catalog) and MLflow
- Databricks Certified Machine Learning Professional — the natural next step once you have production platform experience
- AWS Certified Machine Learning – Specialty or Google Cloud Professional Machine Learning Engineer — general cloud-ML certs commonly held in this role, though adjacent rather than platform-tooling-specific
No dedicated "ML platform engineering" certification exists — the Databricks ML Associate cert is the closest real match given its direct feature-store and MLflow content. Be honest that the AWS/GCP certs validate cloud-ML breadth generally, not this specialisation specifically.
Bootcamps & Training
View list — coming soon- MLOps Zoomcamp (DataTalks.Club) — free, open-source, covers the full ML lifecycle from experimentation to deployment/monitoring
- Made With ML (Anyscale) — has a dedicated Feature Store module covering the exact central-repository pattern this role is built around
- DeepLearning.AI's Machine Learning Engineering for Production (MLOps) Specialization (Coursera) — widely recognised, though more pipeline/production-focused than platform-building specifically
No bootcamp targets ML platform engineering as narrowly as the role itself — these three are the closest, most genuinely relevant free/structured options currently available.
Portfolio & Other
View list — coming soon- A mini feature store or training-orchestration tool, built and documented like a real internal product — README, API docs, architecture diagram
- A working integration with a real experiment-tracking tool (MLflow or Weights & Biases) on a project with more than one model version
- Evidence of API/SDK design thinking, not just a trained model — this role's output is tools other engineers use, and hiring managers look for that framing specifically
- A written explanation of a design trade-off you made (e.g. online vs. offline feature serving) — mirrors exactly what real interviews probe for
Real postings ask candidates to "build the reusable system... the feature store, the registry, the serving layer, the SDK" — a portfolio piece framed as a tool for other engineers, not a trained model, is what actually matches what this role hires for.
Your Roadmap
7 stepsSoftware Engineering Fundamentals
6–8 weeksThis role is software engineering first, ML-flavoured second. Real postings (Reddit's ML Feature Platform team especially) expect fluency in API design and distributed systems basics before any ML-specific tooling knowledge.
Skills to learn
One Cloud Platform & ML Certification
4–6 weeksPick one major cloud (AWS, GCP, or Azure) and pair it with that platform's ML certification. Databricks' Machine Learning Associate cert is the single most directly relevant credential here — its exam explicitly covers feature stores and MLflow.
Skills to learn
Feature Store Concepts & a Real Tool
4–5 weeksThe feature store is the platform's centrepiece — a central, reusable repository of ML features shared across teams. Learn the concept, then get hands-on with Feast (open-source, self-managed) or understand Tecton (managed, sub-100ms serving).
Skills to learn
Experiment Tracking
3–4 weeksMLflow and Weights & Biases are the two dominant real tools across every posting found — learn to instrument training runs, compare experiments, and make results reproducible for the ML engineers who'll depend on your platform.
Skills to learn
Model Registry & Versioning
3 weeksA model registry is how a platform tracks which model version is in production, staging, or archived — reinforced directly in Databricks' ML Associate certification content.
Skills to learn
CI/CD & Orchestration for ML Pipelines
5–6 weeksOrchestration tools that come up repeatedly in real postings: Kubernetes, Kubeflow, Metaflow, Argo Workflows, and Ray. Learn at least one deeply enough to build a CI/CD pipeline for a model end to end.
Skills to learn
Build & Document a Portfolio Platform Tool
4–6 weeksBuild a mini feature store or training-orchestration tool with real documentation — README, API docs, architecture diagram. This directly mirrors what real postings ask candidates to demonstrate: "build the reusable system... the feature store, the registry, the serving layer, the SDK."
Skills to learn
Start here this week
This week: read Uber's Michelangelo engineering blog post end to end — it's the most-cited real artifact in this space, free, and gives you the vocabulary (feature store, model registry, serving layer) that shows up in every real posting. Then spin up Feast, the open-source feature store, locally against a toy dataset — it's the standard "hello world" for this space and takes an afternoon, not a week.
For a structured path: solidify software engineering fundamentals first if they're not already strong, then work through a cloud ML certification (Databricks' Machine Learning Associate is the most directly relevant, since its exam explicitly covers feature stores and MLflow), layer in experiment tracking and model registry tools, and build a real portfolio project — a mini feature store or training-orchestration tool with a proper README and architecture diagram, mirroring exactly what real postings ask candidates to demonstrate.
Pay
U.S. Department of Labor data for the nearest BLS occupation, Software developers. BLS has no occupation for this exact title, so treat these as a benchmark.
Median: U.S. Bureau of Labor Statistics, Occupational Employment and Wage Statistics (median wage, May 2024) and Employment Projections (2024–34). Levels: U.S. Department of Labor Office of Foreign Labor Certification prevailing wage levels (wage year 2025, typical metro), a base-wage benchmark for the metro in the middle of 511 areas, not an offer. See every metro.
Job Titles at Each Level
Entry
Machine Learning Platform Engineer
Mid
ML Platform Engineer / Feature Platform Engineer
Senior
Senior Machine Learning Platform Engineer / Staff Machine Learning Platform Engineer
Steps Overview
- 1
Software Engineering Fundamentals
6–8 weeks
- 2
One Cloud Platform & ML Certification
4–6 weeks
- 3
Feature Store Concepts & a Real Tool
4–5 weeks
- 4
Experiment Tracking
3–4 weeks
- 5
Model Registry & Versioning
3 weeks
- 6
CI/CD & Orchestration for ML Pipelines
5–6 weeks
- 7
Build & Document a Portfolio Platform Tool
4–6 weeks
Explore more roadmaps
Not sure this is the right path? Browse all tech career roadmaps.
View Similar RoadmapsBuilt a project while following this roadmap?
Turn it into a hiring-ready case study in 10 seconds — free.
Ready to explore more?
Browse all career roadmaps across tech, business, and creative fields.