Data Engineer Career Roadmap
Data engineering is the plumbing behind every dashboard, model, and report a company runs on — unglamorous by design, and quietly one of the highest-leverage jobs in tech precisely because everything else breaks silently when it fails. You'll build pipelines that move data from wherever it's born to wherever it's needed, reliable and fast enough that data scientists, analysts, and product teams stop noticing the plumbing exists. The job rewards people who'd rather debug the thing that broke at 2am than argue about the model consuming its output.
Is this the right path for you?
Data engineers arrive from three main directions: backend software engineers who gravitate toward data-heavy systems work, data analysts who got tired of waiting on someone else to build the pipeline and learned to build it themselves, and self-taught career changers who came up through a data-engineering-specific bootcamp or certification path. None of these paths is more legitimate than another — what matters is whether you can reason about a pipeline as a system, not just a script.
If you're the kind of person who'd rather fix the thing that silently broke at 2am than debate the accuracy of the model consuming its output, you're already thinking like a data engineer. The job is closer to backend software engineering and systems thinking than to data science — schema drift, backfills, and idempotency matter more day to day than statistics or machine learning.
Honest note: the bar has risen. dbt and modern cloud warehouses turned what used to require a whole data engineering team into something a single analytics engineer can partially self-serve, which means even entry-level postings increasingly expect Airflow, dbt, and at least one cloud warehouse from day one — not just SQL and a willingness to learn. Career switchers should expect a real adjustment period; most reach parity with CS-degree peers within three to five years, not three to five months.
Career Progression
Where does this role lead?
Click any role to explore timeline, key skills and, where the Department of Labor publishes it, pay.
Entry
Junior Data Engineer
~1–2 yrs
$74,464 (Level I)
You're maintaining and extending existing pipelines under guidance. Understanding why a pipeline is built the way it is matters more than shipping something new.
Key skills
Pay shown is the U.S. Department of Labor prevailing wage for Level I (entry), Level III (mid) and Level IV (senior) in the nearest BLS occupation, base wage for the typical metro, wage year 2025, shown for the main track only. It is a benchmark, not an offer; branches and lead, staff and executive stages have no official figure.
Visual roadmap
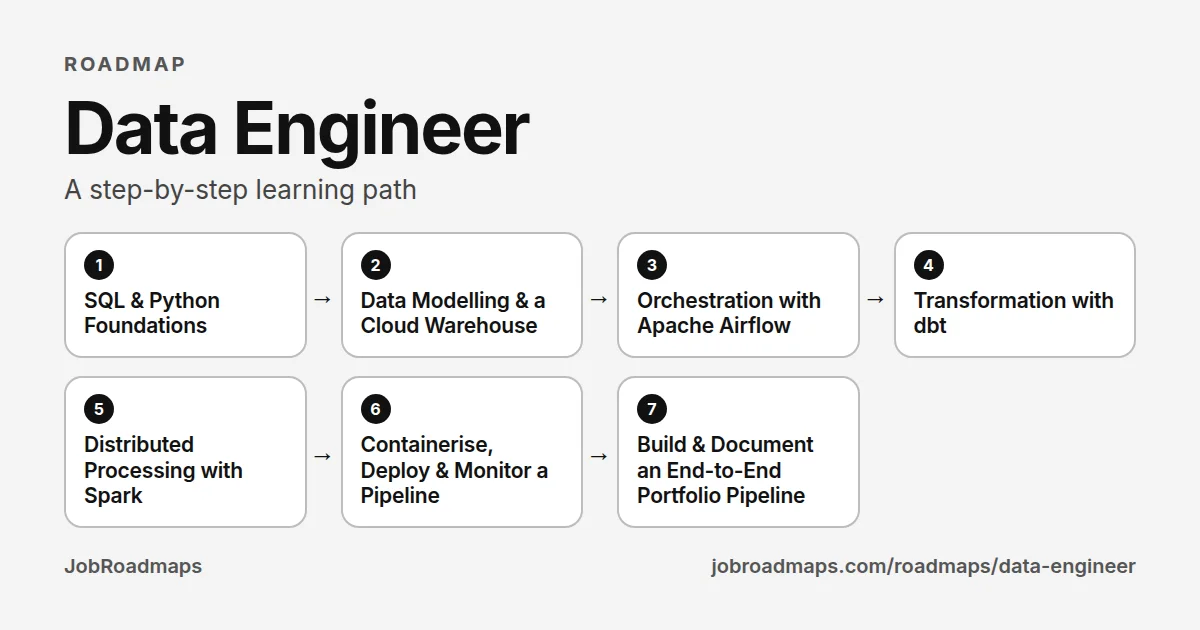
Data Engineer learning path
Work down the line, one step at a time. Tick each skill as you can do it.
- 1
SQL & Python Foundations
6–8 weeksSQL is the daily language of data engineering — joins, window functions, and query optimisation, not just SELECT statements. Python fills in scripting, API calls, and file handling. Together these cover most of what a real data engineering interview actually probes.
Skills to learn
- SQL (joins, CTEs, window functions)
- Query optimisation & indexing
- Python scripting
- pandas basics
- API & file handling
- Git & version control
Start with
- 2
Data Modelling & a Cloud Warehouse
4–6 weeksLearn dimensional modelling — star and snowflake schemas, slowly changing dimensions — then go hands-on with one real cloud warehouse. BigQuery has the most generous free tier, making it the easiest to actually practise on without a company account.
Skills to learn
- Dimensional modelling
- Star & snowflake schemas
- Snowflake, BigQuery, or Redshift
- Partitioning & clustering
- Warehouse cost & performance basics
Start with
- 3
Orchestration with Apache Airflow
3–4 weeksReal pipelines don't run themselves — they're scheduled, monitored, and retried automatically. Airflow is still the dominant orchestration standard: learn to write DAGs, handle failures and backfills, and reason about task dependencies.
Skills to learn
- Airflow DAGs
- Task dependencies & scheduling
- Retries & backfills
- Sensors & operators
- Alerting on pipeline failure
Start with
- 4
Transformation with dbt
3–4 weeksdbt turns SQL into a testable, documented, version-controlled transformation layer sitting on top of your warehouse — the modern standard for the "T" in ELT. Learn models, tests, and automatic documentation generation.
Skills to learn
- dbt models & materialisations
- dbt tests
- Jinja templating
- Auto-generated documentation
- CI for dbt projects
Start with
- 5
Distributed Processing with Spark
4–6 weeksWhen data outgrows what a single warehouse query handles efficiently, Spark is the standard answer. Learn PySpark for large-scale transformations, partitioning strategy, and — just as important — when Spark is overkill for the problem in front of you.
Skills to learn
- PySpark
- RDDs vs DataFrames
- Partitioning & shuffling
- Spark SQL
- Recognising when NOT to use Spark
Start with
- 6
Containerise, Deploy & Monitor a Pipeline
2–3 weeksA pipeline that only runs on your laptop isn't a real pipeline. Package it with Docker, deploy it to a real cloud environment, and wire up basic monitoring and alerting — the step most self-taught learners skip, and exactly the step that makes a portfolio project credible to a hiring manager.
Skills to learn
- Docker basics
- Cloud deployment (AWS/GCP free tier)
- Logging & monitoring
- Alerting on failure
- Environment & secrets management
Start with
- 7
Build & Document an End-to-End Portfolio Pipeline
4–6 weeksOne real, deep, end-to-end pipeline — ingest a real dataset, transform it, load it into a warehouse, orchestrate it, and document the whole thing on GitHub — is worth more than five shallow tutorials. Treat it like a work sample a hiring manager will actually read.
Skills to learn
- End-to-end pipeline design
- Real public dataset ingestion
- README & architecture diagrams
- GitHub portfolio presentation
- Explaining trade-offs in interviews
Start with
jobroadmaps.com/roadmaps/data-engineer · Pay, demand and employer data for this role are further down the page.
Job Market Insights for Data Engineer
Data-backed
What do employers actually ask for?
Read from live job postings — how often each credential is named, from rare to almost always.
"Computer Science background" is the most common credential named, yet it appears only rarely in what we could read. Postings that state it are the minority, but these counts are a floor, so do not read this as "no one asks".
Some postings say outright that equivalent experience or a self-taught route is accepted. That wording is worth reading closely when you see it.
Our read: a portfolio that proves the skill, and a referral from someone inside the company, usually carry more weight than a credential match on paper. That is judgement, not something these counts measure.
Requirement
How often named
Computer Science background
Bachelor's degree
Equivalent experience accepted
Master's degree
Our read: how often a credential is named is not how strictly it is enforced. Equivalent experience, a standout portfolio, or a referral often counts for more than the credential listed.
Data-backed
Which skills appear most in job postings?
Read from live job postings, ranked from most to least often named.
SQL is the most-named skill. Common, but not universal: many postings do not list it.
Past the fundamentals, 5 specialisation skills (SQL included) start separating candidates who can do the job from candidates who have done it. The 15 niche skills are named rarely enough that knowing them is upside, not prerequisite.
Skill
How often named
data quality
documentation
testing
data governance
data modeling
analytics engineering
data lake
business intelligence
version control
code review
distributed systems
ETL pipelines
data warehousing
schema design
monitoring and alerting
Sorted by how often named · JobRoadmaps
Data-backed
Which tools and artifacts appear most in job postings?
Read from live job postings, ranked from most to least often named.
Databricks is the most-named tool, but no tool is a universal requirement here.
Tool / Artifact
How often named
Salesforce
Hex
CI/CD
Looker
Fivetran
Sorted by how often named · JobRoadmaps
Industry overlay
Targeting a specific industry?
The core roadmap gets you through the door anywhere. The difference between "qualified" and "they hired someone else" often lives in industry-specific context — the norms, the compliance floors, the tools assumed fluent in that sector.
Real-time streaming pipelines
Transaction and fraud-detection systems need sub-second data freshness — Kafka and Flink expertise is a baseline, not a differentiator, at fintechs.
Data lineage & audit trails
Financial regulators require provable, reconstructable lineage for every number in a report — pipelines are built for auditability from day one, not bolted on afterward.
Idempotency & exactly-once processing
Double-processing a payment event is a real financial loss, not just a bug — exactly-once semantics and idempotent pipeline design are non-negotiable.
PCI-DSS-aware data handling
Pipelines that touch card data must isolate and tokenise sensitive fields long before they reach a warehouse analysts can query.
Feature stores for fraud ML
Fraud models need low-latency access to fresh behavioural features — data engineers build and maintain the feature-serving infrastructure ML teams depend on.
Companies hiring:
StripePlaidAffirmproduct metrics and telemetry
Core responsibility: instrumenting events, building canonical product metrics, and enabling product teams to make data-driven decisions.
user journey tracking
Understanding cohorts, funnels, and retention requires tracking user behavior across sessions and products.
self-serve analytics
SaaS teams need accessible dashboards and metrics; semantic layers and metric frameworks enable non-technical users to explore data.
Companies hiring:
LinearAsanaIntercomKlaviyoClickUpWebflowOpenAIAnthropicIndustry premiums based on aggregated job posting data · Updated quarterly
Interactive
How ready are you right now?
Check the skills you already have to see your current job-market fit.
The most-named skill for this role is SQL, so a gap there costs you the most. No single skill dominates, but each gap narrows which postings fit you. Check what you already have to see your biggest current gap.
Readiness Check
Check the skills you already have
0/5
base skills
Your biggest gap: SQL, the most often named of the skills you have not ticked.
Start there, then work down the list.
Books worth reading as a Data Engineer
Where to start, in order. The full list of 12, grouped by career stage, is on its own page.
Getting started
Fundamentals of Data Engineering
by Joe Reis, Matt Housley · 2022
Maps the data engineering lifecycle: generation, ingestion, storage, transformation and serving, plus security and orchestration. Read it first to get the whole field in view before choosing tools.
View book →
Learning SQL: Generate, Manipulate, and Retrieve Data
by Alan Beaulieu · 2005
~380 pages~10 hrs to read
Teaches queries, joins, grouping, subqueries and data modification from scratch with clear examples. SQL is the daily language of the job, so work through it early.
View book →
Doing the job

The Data Warehouse Toolkit: The Definitive Guide to Dimensional Modeling, 3rd Edition
by Ralph Kimball, Margy Ross · 1996
~600 pages~15 hrs to read
The standard text on dimensional modelling: star schemas, fact and dimension tables, slowly changing dimensions and industry case studies. Read it once your pipelines work and you need to shape the data for analysts.
View book →
Data Pipelines with Apache Airflow
by Bas P. Harenslak, Julian Rutger de Ruiter · 2021
~330 pages~8 hrs to read
Covers writing, scheduling, testing and deploying workflows in Airflow, including custom components and cloud deployment. Read it when you start orchestrating pipelines for real.
View book →
Senior and leading

Designing Data-Intensive Applications
by Martin Kleppmann · 2017
~620 pages~16 hrs to read
Explains storage engines, replication, partitioning, transactions and stream and batch processing, and the trade-offs between them. Read it when you design the systems that data and models run on.
View book →
Streaming Systems: The What, Where, When, and How of Large-Scale Data Processing
by Tyler Akidau, Slava Chernyak, Reuven Lax · 2018
~350 pages~9 hrs to read
Builds the concepts behind stream processing: event time, windowing, watermarks and exactly-once semantics. Read it when you design or review real-time data systems.
View book →
All 12 books for a Data Engineer →Browse all books →
Some book links are affiliate links: we earn a small commission if you buy, at no cost to you. It does not affect what we list.
Prerequisites & Education
What credentials do employers look for?
These are the most common paths into this role — no single one is required.
Education Level
View list — coming soon- Bachelor's in Computer Science, Information Systems, or a related field
- Bachelor's in Mathematics, Physics, or Engineering with strong programming skills
- Self-taught with a data-engineering-specific bootcamp and a real portfolio pipeline
- No degree with demonstrable production pipeline experience — rarer, but viable
Companies care more about whether you can reason about a pipeline as a system than about your degree. A CS background helps at large tech companies with ATS degree filters, but it isn't a hard gate the way it often is for pure software engineering.
Certifications
View list — coming soon- Google Cloud Professional Data Engineer — the most respected vendor cert, requires real hands-on GCP experience (BigQuery, Dataflow, Composer)
- AWS Certified Data Engineer – Associate — replaced the retired "Data Analytics – Specialty" cert in 2024; the current AWS-track credential
- Databricks Certified Data Engineer Associate / Professional — increasingly requested at companies running a Databricks/Spark stack
- Snowflake SnowPro Core — worth adding if targeting companies on a Snowflake-centric stack
Cloud and platform certifications carry real signal here, more so than in generalist software roles — data engineering job postings frequently name a specific warehouse or cloud platform, and the matching cert shows you already speak that stack.
Bootcamps & Training
View list — coming soon- DataExpert.io (Zach Wilson) — the most reputable data-engineering-specific bootcamp brand, with free and paid cohort tracks
- Dataquest — self-paced, structured "Data Engineering" path distinct from its generic data-science tracks
- DataCamp — data engineer career track covering SQL, Python, and pipeline tools end to end
- Generic "data science" bootcamps (Springboard, General Assembly) are not data-engineering-specific — confirm a program has a distinct DE track before enrolling for this goal
Data-engineering-specific programs are newer and less numerous than data-science bootcamps generally — vet carefully that the curriculum covers orchestration and warehousing, not just Python and pandas.
Portfolio & Other
View list — coming soon- One real end-to-end pipeline on GitHub: ingest → transform → warehouse → orchestrate, fully documented
- A deployed pipeline running on a schedule (Airflow) against a real or public dataset, not just a local script
- dbt models with tests and generated documentation, published alongside the pipeline code
- A written README explaining architecture decisions and trade-offs — rare at entry level, and disproportionately impressive when done well
One deep, real, end-to-end pipeline outweighs five shallow tutorial projects. Hiring managers can tell the difference immediately — deployment, monitoring, and documentation are what separate a portfolio piece from a script that ran once.
Your Roadmap
7 stepsSQL & Python Foundations
6–8 weeksSQL is the daily language of data engineering — joins, window functions, and query optimisation, not just SELECT statements. Python fills in scripting, API calls, and file handling. Together these cover most of what a real data engineering interview actually probes.
Skills to learn
Data Modelling & a Cloud Warehouse
4–6 weeksLearn dimensional modelling — star and snowflake schemas, slowly changing dimensions — then go hands-on with one real cloud warehouse. BigQuery has the most generous free tier, making it the easiest to actually practise on without a company account.
Skills to learn
Orchestration with Apache Airflow
3–4 weeksReal pipelines don't run themselves — they're scheduled, monitored, and retried automatically. Airflow is still the dominant orchestration standard: learn to write DAGs, handle failures and backfills, and reason about task dependencies.
Skills to learn
Transformation with dbt
3–4 weeksdbt turns SQL into a testable, documented, version-controlled transformation layer sitting on top of your warehouse — the modern standard for the "T" in ELT. Learn models, tests, and automatic documentation generation.
Skills to learn
Distributed Processing with Spark
4–6 weeksWhen data outgrows what a single warehouse query handles efficiently, Spark is the standard answer. Learn PySpark for large-scale transformations, partitioning strategy, and — just as important — when Spark is overkill for the problem in front of you.
Skills to learn
Containerise, Deploy & Monitor a Pipeline
2–3 weeksA pipeline that only runs on your laptop isn't a real pipeline. Package it with Docker, deploy it to a real cloud environment, and wire up basic monitoring and alerting — the step most self-taught learners skip, and exactly the step that makes a portfolio project credible to a hiring manager.
Skills to learn
Build & Document an End-to-End Portfolio Pipeline
4–6 weeksOne real, deep, end-to-end pipeline — ingest a real dataset, transform it, load it into a warehouse, orchestrate it, and document the whole thing on GitHub — is worth more than five shallow tutorials. Treat it like a work sample a hiring manager will actually read.
Skills to learn
Start here this week
This week: pick one free-tier cloud warehouse (BigQuery's is the most generous) and load a real public dataset into it today. Then write ten real SQL queries against it involving joins and window functions — not tutorial exercises, actual questions you're curious about. The disorientation of working with real, messy data instead of a clean tutorial dataset is the whole point, and it's better to feel it now than in an interview.
For a structured path: spend six to eight weeks on SQL and Python fundamentals, then move through a cloud warehouse, Airflow, and dbt in sequence — each one builds on the last. Start a public GitHub repo now, even if it's just a README describing the pipeline you intend to build, and treat every project like a work sample a hiring manager will actually read, not a checkbox to tick off a syllabus.
Pay
U.S. Department of Labor data for the nearest BLS occupation, Software developers. BLS has no occupation for this exact title, so treat these as a benchmark.
Median: U.S. Bureau of Labor Statistics, Occupational Employment and Wage Statistics (median wage, May 2024) and Employment Projections (2024–34). Levels: U.S. Department of Labor Office of Foreign Labor Certification prevailing wage levels (wage year 2025, typical metro), a base-wage benchmark for the metro in the middle of 511 areas, not an offer. See every metro.
Job Titles at Each Level
Entry
Data Engineer / Junior Data Engineer / ETL Developer
Mid
Analytics Engineer / Data Platform Engineer / Big Data Engineer
Senior
Senior Data Engineer / Staff Data Engineer / Data Engineering Lead
Steps Overview
- 1
SQL & Python Foundations
6–8 weeks
- 2
Data Modelling & a Cloud Warehouse
4–6 weeks
- 3
Orchestration with Apache Airflow
3–4 weeks
- 4
Transformation with dbt
3–4 weeks
- 5
Distributed Processing with Spark
4–6 weeks
- 6
Containerise, Deploy & Monitor a Pipeline
2–3 weeks
- 7
Build & Document an End-to-End Portfolio Pipeline
4–6 weeks
Explore more roadmaps
Not sure this is the right path? Browse all tech career roadmaps.
View Similar RoadmapsBuilt a project while following this roadmap?
Turn it into a hiring-ready case study in 10 seconds — free.
Ready to explore more?
Browse all career roadmaps across tech, business, and creative fields.